Machine learning sounds complicated until you realize that many systems learn in ways that are surprisingly familiar.
Sometimes a computer is shown examples with the correct answers. Sometimes it receives a pile of information and must discover patterns by itself. In other situations, it learns by trying different actions and seeing what works.
These approaches are known as supervised learning, unsupervised learning, and reinforcement learning. They represent three important ways machines can learn from data and experience.
The difference between them mostly comes down to the type of feedback available during training.
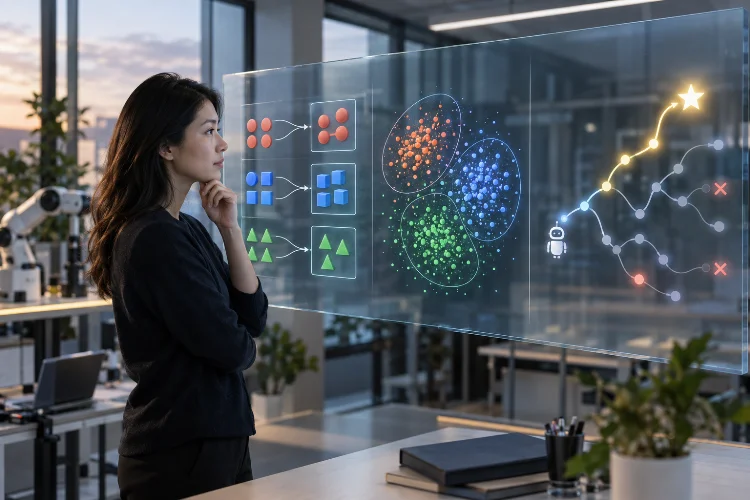
Supervised learning works with labeled examples, unsupervised learning searches for structure in unlabeled data, while reinforcement learning teaches an agent through rewards and consequences.
Understanding these methods is useful even if you are not a data scientist. They influence recommendation engines, fraud detection, customer segmentation, robotics, autonomous systems, forecasting, and many other AI applications.
Let’s look at each approach without getting lost in complicated mathematics.
What Is Supervised Learning?
Supervised learning is probably the easiest type of machine learning to understand because it resembles learning with a teacher.
The algorithm receives training examples that include both the input information and the correct answer, commonly called a label or ground truth. It uses these examples to learn relationships that can later be applied to new data.
Imagine teaching an AI system to recognize whether an email is spam.
The training dataset might contain thousands of emails marked either spam or not spam. The model analyzes patterns involving words, links, senders, formatting, and other features.
Eventually, it learns how those features relate to the labels. When a completely new email arrives, the model predicts which category it belongs to.
Classification vs. Regression
Most supervised learning problems fall into two broad categories.
Classification predicts categories. Examples include identifying fraudulent transactions, recognizing objects in photographs, or deciding whether a customer is likely to cancel a subscription.
Regression predicts numerical values. A regression model might estimate house prices, electricity demand, delivery times, or future sales.
Google’s Machine Learning Crash Course, for example, explains classification as predicting which class or category an example belongs to.
The biggest advantage of supervised learning is clear evaluation. Because the correct answers are known, developers can compare predictions against reality and measure performance.
Its weakness is the need for labeled data. Creating thousands or millions of accurate labels can become expensive and time-consuming.
What Is Unsupervised Learning?
Unsupervised learning takes away the teacher.
Instead of receiving data with predetermined answers, the algorithm receives unlabeled data and searches for patterns, similarities, relationships, or structures by itself.
Consider an online retailer with data from 100,000 customers.
The company may know how often customers shop, how much they spend, which categories they purchase, and when they visit the website. However, nobody has labeled each person as a particular “type” of customer.
An unsupervised learning algorithm can analyze the information and identify natural groups.
Perhaps one group contains occasional bargain shoppers, another includes loyal high-value buyers, and another consists of customers primarily interested in certain product categories.
This process is known as clustering.
Other Unsupervised Learning Tasks
Clustering is not the only application.
Unsupervised techniques can also perform dimensionality reduction, where complicated datasets containing many variables are represented with fewer dimensions while preserving useful information.
They can support anomaly detection, exploratory analysis, association discovery, and other tasks where developers do not already know exactly what patterns they are looking for.
IBM describes clustering, association, and dimensionality reduction as major categories of unsupervised machine learning.
The major advantage is that developers do not need manually labeled datasets.
The downside is interpretation. An algorithm may discover interesting groups, but humans still need to figure out whether those patterns are actually useful.
What Is Reinforcement Learning?
Reinforcement learning works very differently.
Instead of studying a fixed dataset containing correct answers, an agent interacts with an environment. It performs actions, observes what happens, and receives feedback in the form of rewards or penalties.
Think about teaching an AI agent to play a video game.
The agent might receive points for completing objectives and lose opportunities when it makes poor moves. At first, its behavior could look almost random.
After many attempts, however, it begins discovering which actions produce better long-term results.
This trial-and-error process is the heart of reinforcement learning.
Agent, Environment, Action, and Reward
Most reinforcement learning systems revolve around several concepts.
The agent is the decision-maker. The environment is the world it interacts with. An action is something the agent can do, while a reward tells the system whether an outcome was desirable.
The agent learns a strategy, usually called a policy, that helps it select actions designed to maximize cumulative rewards over time.
This makes reinforcement learning especially useful for sequential decision-making problems where one action affects what happens next.
The Key Differences Between the Three Methods
The easiest way to distinguish these approaches is to ask: What feedback does the machine receive?
Supervised learning has correct answers available during training. If the model predicts that a picture contains a dog when the label says “cat,” the training system knows the prediction was wrong.
Unsupervised learning does not have those labels. The algorithm must discover structure within the data without predetermined correct categories.
Reinforcement learning is different again. Instead of receiving a correct answer for every decision, an agent receives reward signals based on what happens after its actions.
Another major difference involves the goal.
Supervised learning is generally used for prediction. Unsupervised learning is often used for pattern discovery. Reinforcement learning focuses on learning what action to take in a changing environment.
None is universally better. The right approach depends on the problem.
Where Are These Learning Methods Used?
These machine learning techniques appear across many industries.
Banks might use supervised learning to predict whether transactions are fraudulent. Healthcare researchers can train classification models to identify patterns associated with certain diseases, although medical applications require careful validation and human oversight.
Retail companies frequently use unsupervised clustering to create customer segments. Similar techniques can discover unexpected patterns in large collections of behavioral or transaction data.
Reinforcement learning fits situations involving repeated decisions.
Robotics is a classic example. A robot may learn how to navigate an environment by experimenting with different movements and receiving rewards for reaching its destination.
Reinforcement learning concepts have also influenced modern generative AI.
Feedback-based techniques can be used during post-training to shape how language models respond, including methods where human preferences provide signals about which outputs are more desirable.
Real AI systems can also combine multiple learning approaches rather than relying on only one.
The Exploration vs. Exploitation Problem
Reinforcement learning introduces an especially interesting challenge called the exploration-exploitation trade-off.
Suppose you discover a restaurant where you always get a good meal.
You could keep returning because you already know it works. That is exploitation-using existing knowledge.
Alternatively, you could try a completely different restaurant. The meal could be worse, but you might also discover something much better. That is exploration.
An RL agent faces the same dilemma.
It must exploit actions that have produced good rewards while still exploring unfamiliar actions that might produce even better results.
Too much exploration wastes time on poor strategies. Too much exploitation can prevent the agent from finding superior ones.
Managing this balance is one of the central challenges of reinforcement learning and shows why simply rewarding a machine does not automatically make training easy.
How Do You Choose the Right Learning Approach?
Start with the data and the outcome you want.
If you have many examples with reliable labels and want to predict an outcome, supervised learning is usually the natural starting point.
If you have a large dataset but do not know what groups or relationships exist inside it, unsupervised learning may reveal useful structure.
If the problem involves an agent repeatedly making decisions, receiving feedback, and adapting its future behavior, reinforcement learning may be more appropriate.
The available resources also matter.
Producing labeled datasets can be costly. Reinforcement learning environments can require huge numbers of interactions, while unsupervised results can sometimes be difficult to evaluate objectively.
Modern machine learning also includes approaches such as semi-supervised learning and self-supervised learning, which blur some traditional boundaries.
Self-supervised learning, for example, can create supervisory signals directly from otherwise unlabeled data rather than relying completely on manual human annotation.
That approach has become especially important in areas such as natural language processing and computer vision.
Why Understanding These Methods Matters
Machine learning is not one single technique.
When someone says that an AI system “learns from data,” an important follow-up question is: How?
Knowing whether a model learns from labels, hidden patterns, generated objectives, or reward signals tells you much more about what the system can realistically do.
It also helps explain its limitations.
A supervised model is only as reliable as the training labels and data it receives. An unsupervised algorithm may discover correlations that are statistically interesting but practically meaningless.
A reinforcement learning system might discover unexpected ways to maximize its reward if the objective is designed poorly.
Understanding the training method therefore helps users evaluate AI systems more realisticaly rather than treating machine learning as magic.
With supervised, unsupervised, and reinforcement learning explained, the differences become fairly straightforward.
Supervised learning learns from labeled examples, unsupervised learning discovers patterns in unlabeled information, and reinforcement learning develops strategies through interaction, trial and error, and rewards.
Each method solves different kinds of problems. Classification and regression work well when reliable labeled data exists. Clustering and related techniques help explore unknown structures, while reinforcement learning shines when decisions unfold over time.
Real-world AI systems increasingly mix these ideas alongside newer methods such as self-supervised learning.
If you want to continue learning AI, try studying one practical example of each approach next. Understanding how machines are actually trained makes concepts such as neural networks, deep learning, recommendation systems, and generative AI much easier to follow.